
From Firefighter to Forecaster: The Leadership Shift That Changes How You Solve Problems
Great managers don't just put out fires. They learn to see the smoke before the alarm goes off.
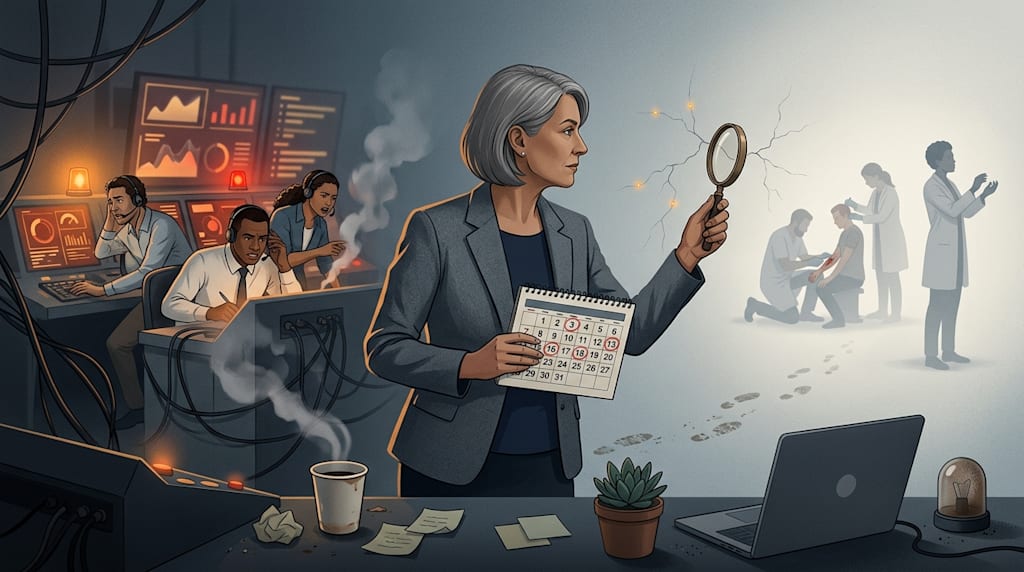
The Next Stage of Leading a Team: From Solving Problems to Discovering Problems
I have a habit: regularly reviewing my calendar to see where my time goes.
After doing this often, I found that most of my time goes to solving problems. Architecture problems, requirements problems, people problems, collaboration problems. One problem after another; by the end of the day I am busy, and I also have a sense of "I made a difference."
Later I started asking another question:
If the things I am busy with now will happen again next month in a similar form, what exactly did I solve today?
This question is not easy to answer. Because it means I cannot only care about "whether the problem was solved"; I also have to care about "where the problem came from," "why it entered my field of view only now," and "can I see it earlier next time."
We always talk about shifting tests left, shifting requirements left. Problems also need to be shifted left.
From starting with a clear task, extend to the time when the problem has not yet been accurately described. From solving a problem that has already surfaced, extend to discovering the signs that have not yet caused losses but are continuously consuming the team.
This is probably a next stage of leading a team: from solving problems to discovering problems.
Where Does the Problem Statement Come From?
When engineers receive a task, they usually consider constraints first.
What throughput must be reached, what range latency must be controlled to, which callers must be compatible, when to go live. The clearer the constraints, the easier it is for technical discussion to converge. Solutions can be compared, work can be split, and results have acceptance criteria.
After entering management, the trouble is: these constraints themselves also need to be checked.
The business proposes halving the response time of an interface. The team can study indexes, caching, concurrency, and computation, and can also reallocate machine resources. This work has engineering value.
But I would first ask: what exactly is the user waiting for?
If completing a task requires going through multiple steps, and this interface accounts for only a small part of the time, then local optimization may not change the user experience. If the wait mainly happens at the manual review stage, continuing to compress server-side time means the investment direction needs adjustment. If the response is already fast enough and users still resubmit repeatedly, we also need to check status feedback and the operation flow.
Performance optimization matters. The question is whether the technical metric the team received is sufficient to represent the result they want to improve.
I often tell business colleagues, commercial colleagues, and other people who raise requirements: state the requirement, not the solution.
Because many people treat their solution as the requirement. They say, "Add an export button for me," but behind it may be "I spend two hours manually organizing data every day." They say, "This API needs to be twice as fast," but behind it may be "users wait too long on this page and give up." They say, "We need to build a middle platform," but behind it may simply be "the data across several systems doesn't match, and I have to reconcile it back and forth every time."
Solutions are not forbidden. But if you start with the solution, the manager loses the chance to check the problem statement.
I would ask them to describe: who encountered what difficulty, under what conditions, what loss it caused, and what evidence exists.
Don't write the solution first.
Managers need to be responsible for where the task comes from. Solution review can only check the solution under a given problem statement; it cannot automatically correct the problem statement itself. If the problem statement is wrong, no matter how elegant the solution, it is only running faster in the wrong direction.
Bian Que's Dilemma
In He Guanzi, Shixian, Bian Que evaluated the medical skill of three brothers, ranking the eldest first, the middle brother second, and himself last. The eldest treated illness before it took shape, the middle brother treated it when the condition was mild, and Bian Que's treatment actions were more visible, so his fame spread farther.
I cite this story to talk about the evaluation problem.
Once a problem becomes severe, the loss is visible, and the handling actions are visible. The system recovers, the business continues to run, and participants can easily understand the value of this work.
Handling things in advance has a problem: we cannot directly observe the result that did not happen.
A team says that after an architecture adjustment, a serious failure was avoided. This claim may hold, or it may just package a worry as an achievement. The absence of a failure may be related to the change, or it may be because traffic did not reach expectations, or because the relevant path was never triggered.
"Prevention is important," everyone agrees. But in resource allocation, preventive investment is often hard to accept. It is not as dramatic as firefighting, nor does it have the clear output of launching a new feature.
Suppose someone proposes that a certain dependency has a single point of risk and needs redundancy. What I want to see is: which functions would be affected if this dependency fails, whether existing alternative paths are available, what conditions are needed for recovery, and how the team has verified it.
Only then do we discuss the cost of adding redundancy, including build, switchover, drills, and ongoing maintenance.
The doctors in the story seem able to accurately identify diseases that have not yet taken shape. Technical management does not have that certainty. We face incomplete information, a changing business, and judgments that may be overturned by new evidence at any time.
Therefore, I prefer to write preventive judgment as three things: what was observed, what was inferred, how it will be verified, and how large the loss is if the judgment is wrong.
Discovering early deserves investment only when both the quality of judgment and the cost of handling are appropriate. Otherwise, "discovering problems early" easily becomes a transfer of the manager's anxiety: I saw a risk, so the team must handle it immediately. In the end, if the risk does not happen, no one can prove the value; if the risk happens, everyone says it was mentioned long ago.
Prevention earns its keep when the risk path has been verified.
Write the Symptoms Clearly
We often see that when a problem is first raised, responsibility is already assigned.
The project is delayed, so execution is insufficient; there is an online error, so quality awareness is lacking; reviews go back and forth, so technical ability is deficient. These explanations easily enter management discussion because they are short enough and easily map to familiar actions: push progress, add reviews, do training.
But they often lack verifiable content.
Take delay as an example. I would first break down the work process: when did the requirement reach a developable state, how long did coding take, how long was spent waiting for joint debugging, at which stage did rework happen, and did the acceptance criteria change?
Suppose a task took two weeks in total, and most of that time was spent waiting for the dependent party to confirm the interface. At this point, asking developers to improve coding efficiency cannot cover the main loss. Continuing to add progress meetings will also take up time that could have been used for coordination and implementation.
However, seeing a long wait time does not mean we can immediately declare "cross-team collaboration is problematic."
The wait may come from unclear interface definitions, from the other party having no resources, or from us starting a task too early when conditions were not yet ready. These situations require different handling. Uniformly adding a coordination role may only add another round of information relay.
We can use the following logic: observed facts, explanations formed based on facts, and actions to be taken.
For example, several tasks stayed at the same dependency stage for a long time. This is a fact. The other party lacks resources. This is an explanation to be verified. Adjusting both sides' schedules is a candidate action. Writing them together will make later discussion accept the earlier speculation by default.
The closer the problem description is to observable behavior, the easier it is for the team to discuss specific changes. Spending a lot of energy explaining "why someone is not responsible enough" usually does not produce an acceptable solution.
Managers must restrain an impulse: to end a discussion that should continue to be broken down with a seemingly profound attribution.
"Insufficient execution" is not analysis. It just gives the problem another name.
Look for Early Signals
Waiting until an accident happens to analyze it often gives relatively concentrated evidence. Looking for early problems means facing much fuzzier signals.
I would first pay attention to the links that have not yet caused losses but continuously depend on extra labor to maintain.
For example, alerts fire frequently and require developers to investigate; every release requires a certain person to confirm manually; a certain type of data must be patched once a day; only a fixed person dares to modify a module; a project can be delivered on time, but only if testing is temporarily canceled or acceptance is compressed.
These phenomena are not enough to prove that the system is about to spin out of control, but they deserve further checking. Because the current result contains undocumented manual investment.
If I only look at whether delivery is complete and whether the service is available, I cannot know how much compensatory labor the team paid to maintain these results.
I would have the team record a few types of information at low cost: repeated manual operations, time waiting for external decisions, unplanned work, and items that can only be completed by relying on specific people. The purpose of recording is to find where repetition occurs, not to slice each person's day into dozens of time segments.
If the granularity is too fine, recording becomes a burden, and the data easily distorts around assessment requirements.
Observation of technical systems requires similar trade-offs. I would not require detailed logs on all paths just because I worry about missing something. Sampling ratio, retention time, number of fields, and query requirements all need to correspond to specific diagnostic questions, and collection overhead and storage costs need a budget.
If a new set of data cannot answer any decision question, I tend to not collect it first.
Alerts also need to specify follow-up actions. After a metric crosses a threshold, who should intervene, what should they judge, and how long is it allowed to wait? For alerts that cannot answer these questions, I would first put them in the observation scope rather than directly interrupting the on-call person.
Early discovery requires enough information, but it cannot be achieved by infinitely increasing the amount of information. We can work backward from a few high-loss scenarios: before the result deteriorates, do we have a chance to see the change? Can existing information distinguish different causes? How can the missing part be filled in at the lowest cost?
How Deep to Ask
After discovering repeated problems, it is easy to go to another extreme: keep asking why until you get an explanation grand enough.
A release failure can be traced to insufficient testing; insufficient testing can be traced to tight scheduling; tight scheduling can be traced to business pressure; finally it is written as "the organization needs to strengthen its quality culture."
The discussion is complete, but there is still no answer for how to do the next release.
I suggest stopping the analysis at the level that can currently be changed and verified, while recording the higher-level constraints.
Suppose a failure involves a configuration change. After restoring the service, I want to continue to find out: was the configuration validated, could an anomaly be found before release, can the change be rolled back independently, and why did existing checks not cover this path?
If validation is missing, discuss how to add validation. If validation capability exists but was skipped because release time was tight, then we need to check bypass conditions and approval authority. Further up, if every delivery commitment defaults to compressing validation time, the scheduling method must also enter the improvement scope.
These levels can exist at the same time. There is no need to force out a single "root cause."
I care more about which change can cut off a known failure path, which one can shorten recovery time, and which constraints can only be accepted for now.
Adding release review is a common choice, but I would use it cautiously. It continuously takes up the reviewer's time and makes release wait for another person's judgment. If a type of error can be identified by deterministic checks, I would prioritize evaluating automated validation; if it must rely on business context judgment, then manual review has corresponding value.
Automation is also a common strategy, but cost must be considered. An exception that occurs very rarely and takes only a little time to handle each time may not justify a complex process. Conversely, for high-frequency operations with stable rules that rely on manual checks for a long time, I would ask for the reason.
The depth of problem analysis should serve intervention choices. When further asking can no longer change action, I will stop expanding the discussion and turn my energy to verification.
Problems Also Need Scheduling
After the ability to discover problems improves, the to-do list is likely to grow first.
Code has debt, processes have gaps, people have dependencies, and business assumptions have risks. If every discovery must be solved immediately, the team will start a large number of improvement efforts at the same time, and the original delivery plan will lose credibility.
Managers need to take responsibility for "not handling it for now."
To judge whether a problem enters the schedule, I look at several things: what loss has already been caused, how the future loss may expand, how reliable the basis for judgment is, what the handling cost is, and whether postponement will lose room for adjustment.
Simply put, ask one question: what happens if we don't do it, and what does it cost to do it?
That is two questions.
Suppose two improvements can both reduce certain maintenance work. One can be done at any time; the other involves an interface contract that will soon be depended on by multiple teams. Once the latter spreads, migration will require more participants to coordinate. I might prioritize the latter, even if it saves less time immediately.
But I would not stuff all these factors into a precise score and sort by decimal point. Probability, impact, and workload contain many estimates; a formula cannot eliminate uncertainty.
For problems with insufficient information, I would arrange verification work separately.
For example, first spend a limited time window checking call situations, do a capacity experiment, or replay a batch of historical tasks. After verification, decide whether to start the full improvement. Verification tasks need an end condition; they cannot occupy manpower for a long time in the form of "continuous research."
I would also distinguish two decisions: allowing a risk to exist temporarily, and committing to solve it at a certain time. The former needs to record who accepts the risk, the scope of acceptance, and the conditions for rechecking. You cannot put all postponed items into a technical debt list with no deadline, then say after the next incident, "I raised it long ago."
Limited resources can only handle a limited number of problems. A manager's work includes prioritizing, postponing, and rejecting; it cannot only provide an ever-growing list of risks.
Do Limited Verification First
Problems discovered in advance often do not yet have enough evidence to support large-scale improvement. We need to prioritize small experiments that can change judgment.
Suppose the team believes that slow delivery mainly comes from a hard-to-use shared component. Directly rebuilding the component library would require a large investment and a long verification cycle. We can first choose one type of repetitive task, adjust one high-frequency interface, and then compare integration steps, rework counts, and total time.
This experiment does not need to prove that the new solution is better in all scenarios. It needs to answer: does the obstacle identified affect delivery; and after removing the obstacle, did the expected change appear?
In experiment design, we need to especially check comparison conditions.
Are the two tasks similar in complexity, are the participants different, was there extra coaching, and did the new solution receive resources the old solution did not have? If these conditions change, the scope of the conclusion must be narrowed.
If the test tasks are all samples with clear rules and complete information, the conclusion can only cover this type of task. When materials are missing, rules conflict, or judgment is impossible, how the system exits and who takes over must also enter the verification scope.
Limited experiments also have limitations. They may miss low-frequency problems, receive extra attention from the team, or fail to cover the collaboration costs after scale expansion. Therefore, after one experiment passes, I will continue to limit the rollout scope and keep rollback conditions.
I am willing to pay some time for these steps. Compared with replacing the entire process at once, phased verification gives me a chance to correct judgment before investment expands.
Authorization and Intervention
Discovering problems easily creates an impulse in managers: since I have already seen it, handling it myself should be fastest.
In an emergency, this may be an appropriate choice. But if every complex problem eventually comes back to me, I need to check how I intervene.
I would distinguish three links: identifying risk, making decisions, and executing handling. They can be handled by different people.
When a manager discovers a risk in a release link, they can ask for more evidence, determine the owner, and set a completion deadline. Unless the risk has exceeded the team's current capability or requires crossing existing authority, there is no need to take over the entire implementation.
When authorizing, what I need to convey is the goal, constraints, available resources, and under what circumstances escalation is mandatory. For implementation details, I leave room.
There is a cost here. The solution the team chooses may differ from my habits, and local implementation may not be as fast as if I did it myself. If I take the task back every time this difference appears, members will have difficulty accumulating experience in complete judgment.
But authorization cannot become no checking.
I arrange checkpoints according to risk. Local changes that can be easily rolled back allow the owner to move quickly; migrations involving data destruction, cross-team commitments, or difficult rollback need earlier review of the plan and prerequisites. Check frequency changes with risk, avoiding the same intensity of management for all tasks.
I also need to personally participate in some frontline work, such as reading a failure timeline, following up on a long-blocked task, or checking how an improvement is used.
If information only comes from reports organized layer by layer, it is hard for me to judge which costs have been omitted. Personal contact with the frontline is to calibrate judgment; afterward, a clear owner should still complete handling and acceptance.
After discovering a problem, I also owe the team a decision: who is responsible, how much to invest, when to check, and what will not be done because of it.
Let Risks Come Up
If I want the team to report problems in advance, I need to check how I respond to bad news.
After a member raises a risk, they are immediately asked to prove it will definitely happen; after admitting uncertainty in progress, they are judged as lacking responsibility; after discovering a historical defect, they are first asked why it was not found earlier. Facing these responses, a person has reason to wait until the evidence is more sufficient before speaking.
By the time the evidence is sufficient, the room for adjustment may already have shrunk.
I would allow risk reports to retain uncertainty, but require them to be specific: what was observed, what may be affected, what information is still missing, and what support is hoped for.
"This project will definitely be delayed" and "the key dependency has not been confirmed; if it cannot be completed this week, we need to adjust the subsequent joint debugging schedule" contain different amounts of information. The latter expression lets the manager make a decision and also allows later facts to revise the judgment.
For risks raised in good faith that ultimately do not happen, I will not judge the raiser as having made a bad judgment merely based on the result. I will review whether the information at the time was sufficient to support the concern, whether the verification action was reasonable, and whether it did not continue to worsen because it was handled in advance.
Likewise, I will not reward persistent pessimism without evidence. After a risk is raised, someone needs to add information, narrow the scope, and withdraw the judgment when necessary. Only reminding everyone of all possibilities without participating in verification transfers the screening cost to the whole team.
Preventive work also needs evidence for evaluation.
I will check whether the risk path has been verified, whether the improvement covers it, whether rollback or recovery has been checked, and whether follow-up maintenance responsibility has been implemented. As for "how much loss was avoided," if there is not enough basis, I will not write an exaggerated number.
For repeated manual labor, we can compare the number of times and time before and after; for recovery capability, we can record the operations completed and time spent in drills; for collaboration improvement, we can check whether waiting and rework have changed. Evaluation should land as much as possible on records that can be reviewed.
This will add some recording cost. I am willing to keep the parts related to decision-making and acceptance, and I will not require the team to produce complete reporting materials for every improvement.
Check What Has Been Completed
There is another type of problem that is easily overlooked by technical management: the task is completed, but the investment did not produce the expected result.
The system goes live on time, the feature passes acceptance, the interface meets the design, and the team has not made obvious mistakes. A few months later, usage is very low, the original manual process continues, and the new system has an extra maintenance responsibility.
If my check ends at launch, this type of problem will not enter my field of view.
I will agree on a post-investment review when the project is initiated. What specifically to check depends on the problem the project is meant to solve: have manual steps decreased, have users completed tasks that were originally difficult, has the business adopted the new process, and has the old system exited as planned.
"Already launched" cannot replace the answers to these questions.
If the result does not appear, I need to recheck the original assumptions. Perhaps we identified the wrong obstacle, perhaps the solution handled only a small part, or perhaps business conditions have changed. Before adding more features, first confirm whether there is still a basis for additional investment.
Stopping a project is also a choice that needs serious evaluation. It involves existing investment, staffing, and commitment adjustments, and is often more troublesome to handle than approving the next phase. But maintaining a system that lacks a reason to be used will also continuously consume resources.
Discovering problems therefore also includes checking whether the problem the team is solving still exists, whether the solution is still applicable, and whether the goal has already changed.
Time and Self-Review
This will change how I arrange my time.
I still need to participate in failure handling, understand technical details, and be responsible for delivery results. At the same time, I will set aside fixed time to check repeated labor, unverified judgments, and results after launch. For problems that have already surfaced, require closed-loop handling; for problems that are only signs, arrange limited verification; for problems temporarily accepted, leave conditions for rechecking.
I will also regularly review the problems I have raised. How many were supported by evidence, how many were negated, which ones continued to consume the team because a decision was delayed, and which handling actions brought new burdens.
Otherwise, so-called problem discovery easily becomes a manager continuously adding tasks to the team.
From solving problems to discovering problems, for me it means the scope of work has expanded: I need to participate in definition, make trade-offs, and check the original judgment after results appear.
Problems entering the field of view earlier only gives us more room to handle them. Whether this room is used well ultimately still has to return to specific actions and results.
Next time I flip through my calendar, what will I see?
If it is still full of failure handling, requirements review, and progress meetings, it may mean I am still stuck in solving problems. If there are a few more blank spaces, used to read operation logs, look at drill records, and follow up on a feature three months after launch, then it means problems have shifted left a bit.
Just a bit.
About the Creator
Jin
Writer of reamstories
https://reamstories.com/jin
Enjoyed the story? Support the Creator.
Subscribe for free to receive all their stories in your feed. You could also become a paid subscriber, letting them know you appreciate their work.
Comments
There are no comments for this story
Be the first to respond and start the conversation.