
AI Made Answers Free. The People Who Win Now Do 3 Things Differently.
When a machine can answer almost anything, the advantage shifts to asking sharper questions, judging what is true, and connecting ideas nobody else sees.
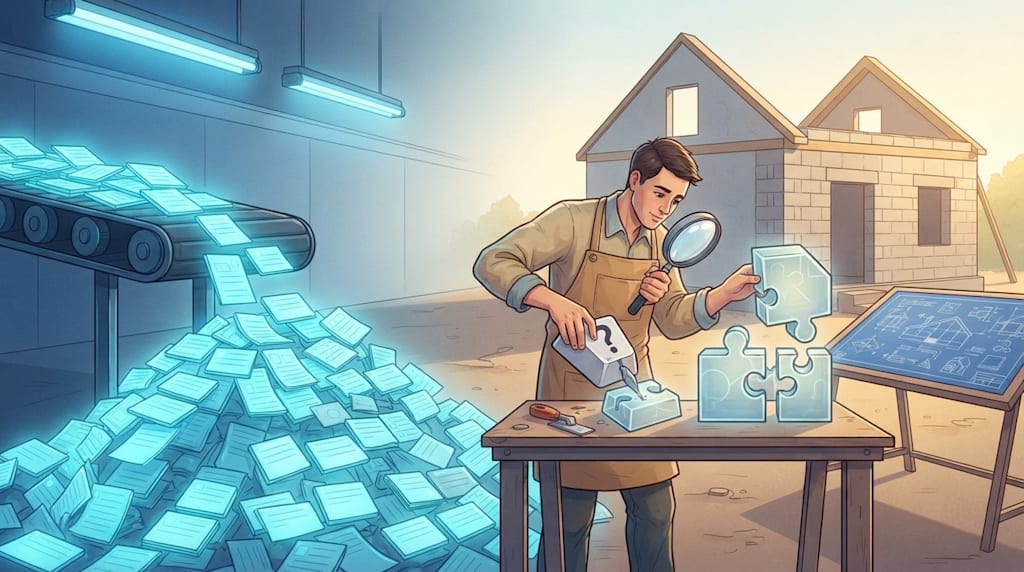
You know the feeling. A question that once cost an afternoon now costs a sentence. The model returns a page, sometimes ten. Definitions, frameworks, examples, counterexamples, a plan you could paste into a slide deck. Answers arrive like tap water. Turn the handle, fill the glass.
The more convenient it gets, the clearer the worry becomes. When answers can be produced in bulk at near-zero cost, the scarce skill is no longer answering. The scarce skills are asking, judging, and connecting.
This essay uses one unit to make that case.
The unit: (question, answer)
A complete unit of meaning is a question paired with its answer. A sentence is too small. A fact is too static. A question without an answer hangs in the air. An answer without a question is a conclusion with no handle. Meaning forms when the two are joined.
Example. “How do I write a good paper?” That is a question, but it is wide enough to swallow a library. The model replies with ten thousand words of correct fog: read widely, structure clearly, revise often, keep a question in mind. Every sentence true. Nothing usable.
Try: “In qualitative research, when moving from grounded theory coding to theory generation, what establishes trustworthiness at that leap?” Now there is an object, a boundary, a step, a dispute. The answer can be argued with. It can be checked. It can fail.
Add context, purpose, constraints. A (Q,A) pair does not float in space. Who asked it? For what purpose? Under what limits? Without those, the pair is dehydrated. This matters when you borrow across fields. Two answers can look alike and share only a metaphor.
Skill one: asking
Many people assume asking is easy. It is not. The model’s weakness is not ignorance. Its weakness is your vagueness. A vague question gets the safest answer: balanced, thorough, harmless, useless. Asking is the act of bounding the problem.
Example. “How do we improve team efficiency?” The model gives chicken soup. “For a 12-person remote R&D team, across three time zones, with requirements changing every week, how can two-week sprints cut delivery delay from 40% to 15%?” Now the model can give tradeoffs, schedules, risks, a testable plan.
Train this. Every day, take one blurry worry and rewrite it into three answerable versions. Force yourself to name the object, the boundary, the variables, the success standard, and a possible counterexample. Do this before you open the model. The question is not a prompt. The question is the work.
Skill two: judgment
The model’s strength is volume. Ask one question, get ten answers. Ask again, get a hundred. Volume is the danger. The more answers arrive, the more you need an eye that can sort them. Which claim is supported? Which contradicts another? Which sounds beautiful and carries nothing? This is judgment.
Judgment does not fall from the sky. It grows from basic training. There is a trap: if AI can do the basics better, why train them? Because judgment is rooted in having done the basics yourself.
You run a regression once, and you can smell an implausible coefficient. You read ten primary papers, and you can tell a secondhand summary from a fabricated citation. You write code once, and you know where the logic will break. You run an experiment once, and you know which difference might be noise.
AI can do the basics faster. It doing them does not give you judgment. The point of basic training was never speed. The point was to grow the seed of judgment.
Four handles:
Evidence level. Raw data or secondhand summary? Peer-reviewed or personal opinion? Systematic review or one case?
Falsifiability. What would prove this wrong? If nothing could, it may be rhetoric, not knowledge.
Interested parties. Who is speaking? Why now? What do they gain, miss, or ignore?
Counterexamples. What evidence runs the other way? What case does the claim fail to cover?
Use them on the model’s output. Use them on your own.
Skill three: creation
Judgment picks the right answer from the pile. Creation connects different answers into something new. The lever is seeing that two unrelated (Q,A) pairs share the same problem-ness. Call it problem equivalence.
Example. A plan for urban traffic congestion. A design for classroom attention loss. One handles cars, the other students. Look lower. Both face: under conflicting constraints, how do you make individual behavior converge toward a better overall state?
Traffic has road capacity, travel time, cost, fairness. Classroom has class hours, attention bandwidth, curriculum pace, student differences. Once you see the shared problem, “staggered schedules + incentives” can inform classroom design. “Immediate feedback” can inform traffic policy.
That is creation. You see that different (Q,A) pairs answer the same deeper question, then join them into a pair no one has seen.
The caution: equivalence is not surface similarity. Traffic congestion and attention congestion both use the word “congestion.” Their mechanisms differ. Equivalence must hold at least at one layer: goal, constraint, mechanism, or mathematical structure. A shared metaphor is not enough. The model is good at producing pretty analogies. Without judgment, creation becomes a collage of hallucinations. Judgment guards the gate.
The loop and the zeroth skill
The three skills form a loop. Asking decides the raw material. Judgment decides what stays. Creation decides what gets combined. The model can accelerate each step. It can generate more candidate questions, more pro and con answers, more cross-domain links. It cannot decide which question matters, which answer to trust, which link to chase.
Behind the loop sits something more basic: intention and responsibility. Why do you want this answer? Who does it serve? What happens if it is wrong? Who carries the cost? The model does not carry consequences. You do.
So there is a zeroth skill: responsible choice. Treat it as a practice. Before you use an answer, write one sentence: “I will use this to do X. If it is wrong, Y happens.” That sentence changes how you read. It turns an answer from entertainment into a decision.
A training list
Ask. Each day, rewrite one vague worry into three answerable versions. Example: “I procrastinate at night” becomes “I scroll on my phone after 9 p.m. How can environment design and task splitting raise my study time from zero to 45 minutes?” The second version can be tested.
Judge. Take one question. Ask the model for the strongest case and the strongest countercase. Then find the primary source, the evidence level, the interested party, and the falsification point. Do not look only at what it says. Look at why it says it, who says it, and what would prove it wrong.
Create. Once a week, do a cross-domain isomorphism. Take two (Q,A) pairs from different fields. Abstract the shared problem-ness. Generate a new plan. Then test it. Example: fitness adherence and user retention. Shared problem: how short-term incentives become long-term identity. Ask whether the equivalence holds. Find its boundary.
Build an idea-unit library. Do not save answers alone. Save (Q,A) pairs. Add context, constraints, and possible equivalences. Over time, you will not have a pile of information. You will have a set of meaning blocks that can be taken apart, recombined, and moved.
Back to the start
Large models did not make us dumb. They outsourced answering. The energy that frees should go to three places: ask precisely, judge accurately, connect different answers into new meaning.
Idea-units are bricks. Problem equivalence is joinery. The model gives you a trainload of bricks. Building the house is yours. Purpose and constraints are the blueprint. Responsibility is the load-bearing wall.
When answers become cheap, human value does not disappear. It moves. From knowing answers to defining questions. From remembering conclusions to judging truth. From repeating knowledge to recombining meaning.
The model will keep answering. Which question is worth asking, which answer is worth trusting, which answers together become a new world. That remains yours.
About the Creator
Jin
Writer of reamstories
https://reamstories.com/jin
Enjoyed the story? Support the Creator.
Subscribe for free to receive all their stories in your feed. You could also become a paid subscriber, letting them know you appreciate their work.
Comments
There are no comments for this story
Be the first to respond and start the conversation.