
Amp Raises 13 Billion to Build AI Compute Grid for Startups and Universities
Aggregated GPU pool challenges hyperscaler lock in as collective bargaining shifts access from capital rich incumbents to coalition based infrastructure model
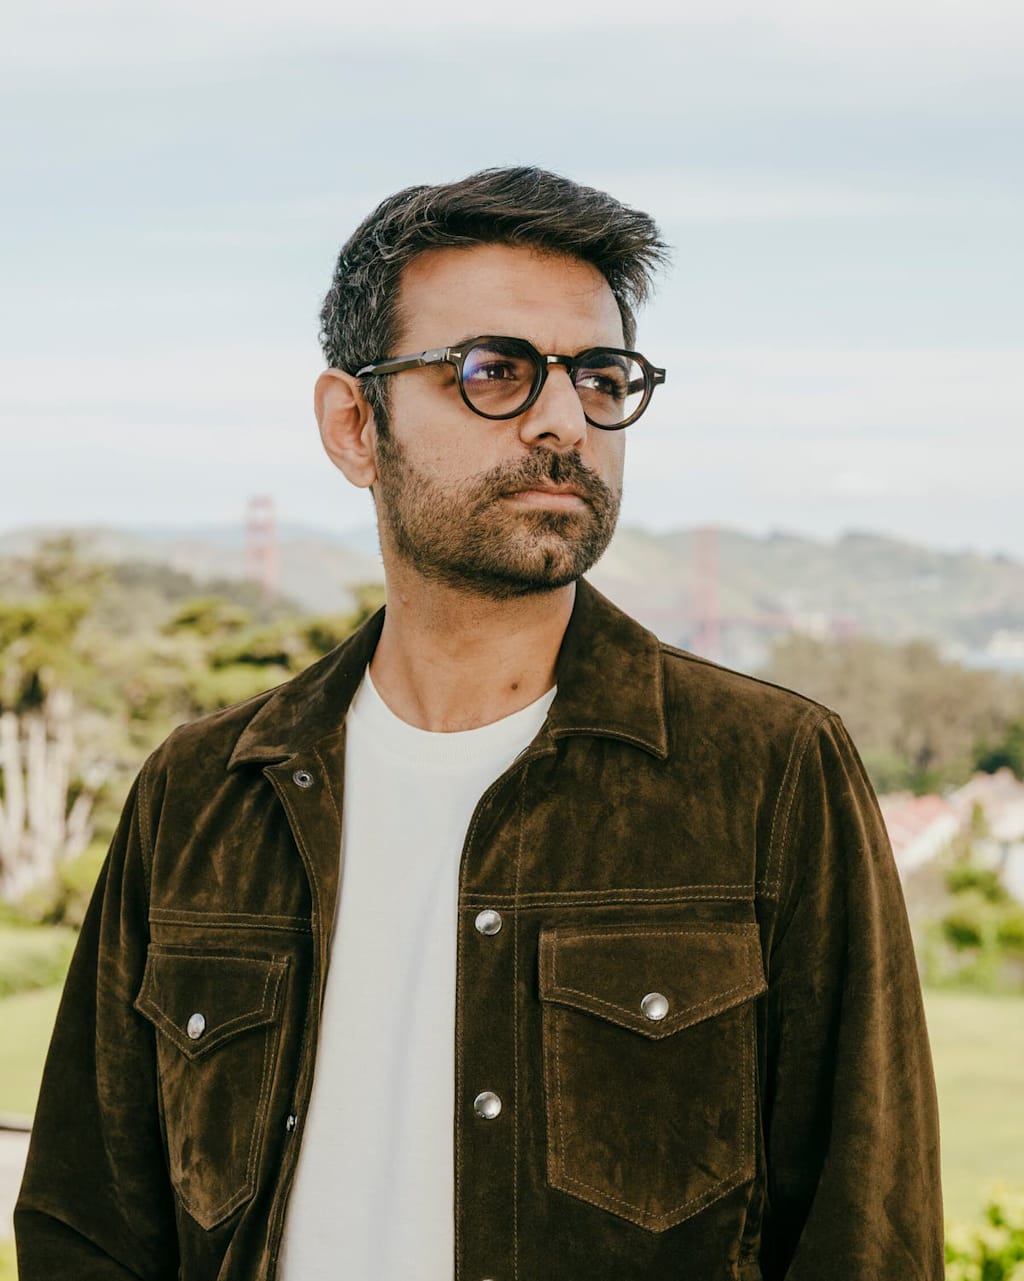
Read Time 6 minutes Tags AI Infrastructure Compute Access GPU Market Amp Andreessen Horowitz Nvidia The world leading artificial intelligence companies are spending hundreds of billions of dollars on the computer data centers needed to create AI Tech giants like Amazon and Google and well funded start ups like Anthropic and OpenAI are among the tiny group of outfits with the money and connections to get access to all that computing power That leaves other organizations out in the cold Anjney Midha a serial tech entrepreneur who was a partner with the venture capital firm Andreessen Horowitz hopes to change that dynamic with an unusual start up His young company Amp is trying to buy extra computing power from data center operators in the United States and other countries so it can share that valuable resource with anyone who needs it Amp based in Menlo Park Calif aims to create a global pool of specialized computer chips that can be used by start ups universities and other organizations that otherwise would not have access to the vast amounts of computing required to train the most powerful AI models Some companies just cannot get the computing power they need Mr Midha said The world wealthiest and most powerful companies are hoarding the infrastructure for themselves Amp has raised more than 13 billion from investors including Andreessen Horowitz the start up incubator Y Combinator and various cloud computing providers Several notable start ups have also agreed to help use and share its pool of computing power including Periodic Labs an AI start up focused on scientific discovery and Eleven Labs which builds AI systems for generating voices Amp is part of a wider effort to pool AI infrastructure The chip maker Nvidia and the French start up Mistral said this year that they would pool computing power for building AI systems for European companies and nations hoping to reduce their dependence on US tech giants Technical and market analysis One Compute pooling as market correction The hyperscaler model centralizes GPU access behind capital intensive cloud contracts Amp replicates the electricity grid model where aggregated demand buys bulk capacity then redistributes it Investors contribute funds that Amp can use to buy computing power from data center operators AI start ups then join the coalition so they can use the computing power to build AI models In return these start ups contribute additional funds or perhaps other resources Some start ups may share digital data needed to train AI models Or they may share the models themselves giving away the core software code to others in the coalition Companies may even work to train models together This changes the unit economics for mid tier labs Training a frontier model requires 10000 to 100000 H100 equivalents for months At hyperscaler list prices that is 100 million to 1 billion in compute alone Amp collective bargaining reduces that cost by negotiating reserved instance rates and absorbing idle capacity from data center operators The risk is underutilization If demand forecasting misses then Amp holds stranded capacity If demand exceeds supply then queue times rise and the advantage erodes Two Strategic leverage for participants The ultimate value of the coalition is collective bargaining said Liam Fedus chief executive of Periodic Labs On its own his start up would struggle to get the computing power it needed But if Amp can negotiate with data center operators on behalf of many start ups it can gain additional leverage When you pool your demand you can have far more serious conversation about buying computing power Mr Fedus said Beyond price the pool offers access guarantees Start ups without hyperscaler relationships often face 6 to 12 month waitlists for reserved capacity Amp pre purchases capacity and allocates it via credit system That reduces time to train and allows faster iteration cycles For universities and nonprofits the pool removes the need to negotiate institutional contracts with AWS Azure or GCP Three Ecosystem and geopolitical implications Amp is part of a wider effort to pool AI infrastructure Nvidia and Mistral announced a similar pool for European companies and nations hoping to reduce dependence on US tech giants The pattern is clear Compute access is becoming a strategic resource analogous to energy and semiconductors Countries and regions that cannot secure domestic capacity will rely on coalitions or face capability gaps This also affects the open source ecosystem Projects like DeepSeek and Llama need training runs to stay competitive If Amp and similar pools provide access then open models can keep pace with closed labs If pools fail to scale then open source lags and capability concentrates further Four Risk and sustainability model The pool model depends on three factors stable supply of GPUs from data center operators predictable demand from members and efficient scheduling across heterogeneous hardware Amp must manage fragmentation across H100 H200 Blackwell and emerging chips from AMD and Intel Scheduling overhead increases with heterogeneity but also creates arbitrage opportunities if models can be optimized for specific silicon Financial sustainability requires either margin on resale or contribution from members in the form of data models or engineering resources If Amp relies solely on arbitrage then margins are thin If it builds value through co development and shared datasets then the moat widens What to watch First utilization rates and queue times within Amp pool If members get compute faster than on hyperscalers then adoption accelerates Second pricing structure versus spot and reserved rates from cloud providers Third geographic expansion Data center operators in US and other countries are part of the network Regulatory risk increases if export controls restrict cross border compute sharing For founders and research labs Amp signals that compute access is no longer gated solely by balance sheet size Collective bargaining can unlock training runs that were previously impossible For hyperscalers it is a signal that the long tail of AI demand is organizing to reduce lock in Do you think compute pooling can sustainably challenge hyperscaler dominance Share your view in the comments
About the Creator
Enjoyed the story? Support the Creator.
Subscribe for free to receive all their stories in your feed.
Comments
There are no comments for this story
Be the first to respond and start the conversation.