
How AI Machines Learn from Data 2024
Understanding the Basics of Machine Learning
Definition of Machine Learning
Machine learning (ML) is a subset of artificial intelligence (AI) that enables systems to learn from data, identify patterns, and make decisions with minimal human intervention. Essentially, it involves training a computational model using a large dataset to recognize complex structures and make predictions or perform decision-making tasks.
Types of Learning: Supervised and Unsupervised
Machine learning can be broadly categorized into supervised and unsupervised learning. Supervised learning involves training a model on a labeled dataset, where the input-output pairs are known. The model learns to map inputs to the correct outputs by analyzing the differences between its predictions and the actual outcomes, a process driven by minimizing a specific loss function. Unsupervised learning, on the other hand, deals with unlabeled data. The model attempts to infer the natural structure present within a set of data points, often used for clustering or association tasks.
The Role of Algorithms
Algorithms are the backbone of machine learning. They are the mathematical instructions that enable a computer to learn from data. Common algorithms include linear regression, decision trees, neural networks, and support vector machines. Each algorithm has its strengths and weaknesses, making it suitable for different types of problems and datasets. The choice of algorithm plays a crucial role in the model's performance and its ability to generalize from the training data to unseen examples.
Data Collection and Preprocessing
Importance of Quality Data
The quality of data is paramount in machine learning. High-quality data can significantly enhance the accuracy and reliability of ML models. It is essential to have data that is representative, complete, accurate, and relevant to the problem being solved. Poor-quality data can lead to misleading insights and underperforming models.
Methods of Data Collection
Data can be collected through various means, including surveys, sensors, web scraping, and database extraction. Selecting the right method of data collection depends on the nature of the problem, the availability of data sources, and the resources at hand. Ethical considerations, such as privacy and consent, are also crucial when collecting data.
Data Cleaning Techniques
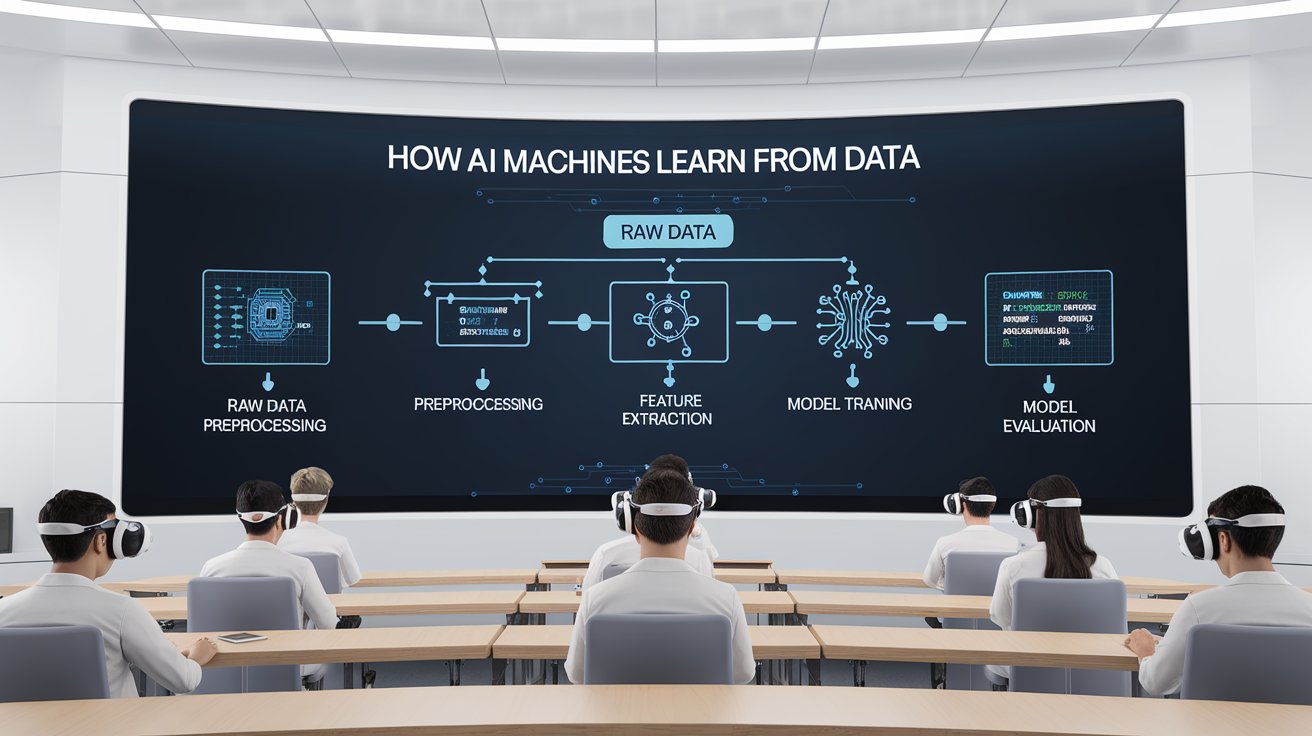
Data preprocessing involves cleaning and transforming raw data into a usable format. This process includes handling missing values, correcting errors, filtering outliers, and normalizing data. Techniques such as imputation, smoothing, and encoding categorical variables are commonly employed to ensure that the data fed into the model is of high quality and suitable for analysis.
Training AI Models
Training Data Sets
Training a model requires a substantial dataset that encapsulates the underlying patterns the algorithm needs to learn. The datasets are typically split into training and validation sets. The training set is used to teach the model, while the validation set assesses its performance.
Model Selection Criteria
Selecting the right model involves considering factors like the nature of the problem, the size and characteristics of the dataset, and computational efficiency. Some models are better suited for linear problems, while others, like deep learning models, excel in capturing non-linear relationships and complex patterns.
Role of Training in Performance
Training is a critical phase in model development. During training, the model iteratively adjusts its parameters to minimize the error between its predictions and the actual outcomes in the training set. Techniques such as gradient descent are employed to optimize the model’s performance. The quality of training directly impacts the model's ability to generalize to new, unseen data.
Evaluation and Validation
Metrics for Model Evaluation
Model evaluation metrics determine how well the model performs. Common metrics include accuracy, precision, recall, F1-score, and Mean Squared Error (MSE). The choice of evaluation metric depends on the specific problem and the importance of different types of errors.
Cross-Validation Techniques
Cross-validation is a robust technique for assessing a model’s performance. It involves partitioning the dataset into multiple folds and training the model on each subset while validating on the remaining data. This process helps in obtaining a reliable estimate of the model’s performance and ensures that the model is not overfitting or underfitting the data.
Overfitting and Underfitting
Overfitting occurs when a model learns the detail and noise in the training data to such an extent that it negatively impacts its performance on new data. Underfitting, on the other hand, occurs when the model is too simple to capture the underlying pattern of the data. Balancing underfitting and overfitting is critical for developing a model that generalizes well.
Deployment and Monitoring
Steps for Model Deployment
Deploying a model involves integrating it into a production environment where it can start making predictions on real-world data. This phase includes steps like selecting a deployment platform, writing APIs for model inference, and ensuring the infrastructure can handle the computational load.
Monitoring Model Performance
Once deployed, continuous monitoring is essential to ensure the model performs as expected. Monitoring involves tracking metrics like prediction accuracy, response time, and resource usage. It also includes setting up alerts for any significant deviation from expected performance.
Ensuring Model Updates
As new data becomes available, the model may need to be updated to maintain its accuracy and relevance. Implementing a pipeline for retraining and redeploying the model ensures it adapts to changing data patterns and continues to perform optimally over time. Regular updates help in mitigating issues from data drift and concept drift.
In summary, understanding how AI machines learn from data involves grasping the fundamentals of machine learning, preprocessing data, effectively training and evaluating models, and managing their deployment and ongoing performance. Successful implementation requires a comprehensive approach that starts with high-quality data and extends to vigilant monitoring and updating of models to adapt to new challenges.
About the Creator
Enjoyed the story? Support the Creator.
Subscribe for free to receive all their stories in your feed.
Comments
There are no comments for this story
Be the first to respond and start the conversation.