
Why Bigger AI Isn’t Smarter
The Fable 5 flop exposes the widening gap between benchmark glory and real‑world value.
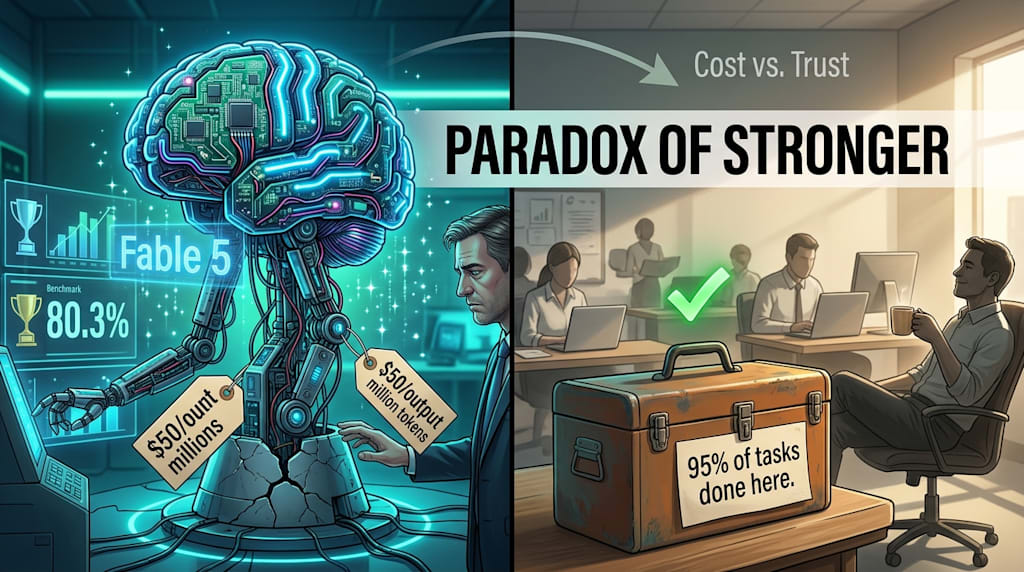
In the summer of 2026, Silicon Valley's AI narrative hit a fork in the road.
Ramp tracked spending data from 70,000 enterprises. Two months after Fable 5's release, corporate customers were spending only 11% of Anthropic's total product revenue on it. The growth curve climbed for a short stretch and then flattened out.
Do the math: Fable 5 costs $10 per million input tokens and $50 per million output tokens—twice the price of Opus 4.8 and 50 times that of DeepSeek V4. On CursorBench 3.2, it scored 70.5% against Opus 5's 70.0%—a half-percentage-point gap. The per-task cost difference is $9—$17.32 versus $8.23. Pay double, get half a point.
Enterprise customers aren't fools.
"Most people don't need to work with the absolute cutting edge," said Miles Clements, a partner at Accel—which has invested nearly $1 billion in Anthropic. This isn't bearishness; it's clarity.
Older models already handle 95% of enterprise tasks. AT&T plans to raise the share of AI workloads carried by open-source models from 40% to 70%. Docusign cut token usage nearly in half by optimizing context. Yum Brands put it bluntly: 95% of the work can be done with cheaper models.
When AI becomes a utility, stability and affordability matter more than IQ.
I. The Generational Test: Does Fable 5 Count as "Fourth-Generation"?
Earlier this year I said something: diminishing marginal returns on model intelligence. Looking back, that was an understatement.
Large language models have roughly gone through three generations:
Gen 1 (Chat-level): GPT-3 and the like—chatty but unreliable, MMLU below 80.
Gen 2 (Knowledge/Logic-level): GPT-4, Claude 3—stable world knowledge and reasoning consistency, MMLU above 80. The first Chinese model to reach this bar was DeepSeek V2.5, playing catch-up in under two years.
Gen 3 (Tool-execution-level): Gemini 3, Opus 4.5—SWE-bench hitting 75%, able to call tools and write code. This generation caught on fast—GPT-5.5 arrived in under six months, and now DeepSeek, Qwen, Kimi, GLM, Meta, and Grok all have Gen-3 capabilities, even the "mini" Qwen 27B.
So does Fable 5 count as Gen 4? No.
The differentiator is no longer tool execution—it's reliability. Can you hand over a closed-loop task and not keep watching?
Self-driving doesn't get to call itself L3 unless the driver dares to play a round of Honor of Kings from the driver's seat. Would you? No? Then don't call it L3.
Fable 5 scored 80.3% on SWE-Bench Pro, blowing past GPT-5.5's 58.6% by more than 20 points. But coding ability is just coding ability. It still requires you to constantly verify its logic. A truly smart employee doesn't turn around after every step to ask, "Did I do that right?" Asking all the time is, in fact, a sign of not being smart enough.
The core of Gen 4 is the sparse reward problem—making correct judgments even in environments with no clear signal of right or wrong. It's about intrinsic judgment—knowing which way to go without excessive validation signals.
The major players have diverged on this front:
Anthropic: Betting on parameter scale plus world knowledge, supplemented with some RSI, hoping judgment will "emerge" from within.
OpenAI: Double down on mathematical logic, fantasizing that mathematical prowess will generalize to other domains.
DeepMind: Roughly aligned with Anthropic's trajectory.
DeepSeek: More aggressive—aiming to skip Gen 4 entirely and go straight to Gen 5 with continual learning. That sounds like fundraising rhetoric. If they actually try it, there's a good chance of a spectacular faceplant.
Being good at math doesn't mean you know how to get things done.
Terence Tao's assessment of Shinichi Mochizuki's proof of the ABC conjecture fits perfectly here. Comparing Mochizuki with Zhang Yitang and Grigori Perelman: Zhang, on page 6 of his paper, gave a nontrivial observation—that improving the Bombieri–Vinogradov theorem for smooth moduli would prove bounded gaps between primes. Perelman, on page 5, reinterpreted Ricci flow as a gradient flow, and by page 7 had established a new theorem. Though still far from proving the Poincaré conjecture, experts could immediately see "there's good stuff in here." Mochizuki's paper? It suffers from the same flaw as countless attempts at grand problems—they keep complicating things until a miracle happens, and that miracle is usually just a mistake.
Fable 5's high score may be nothing more than an "overfitting miracle" in the coding domain, not the awakening of general-purpose judgment.
The real fourth generation hasn't arrived. None of the current approaches have touched the core of the problem.
II. The Value of a Proof of Concept Cannot Be Directly Monetized
But Fable 5 does have value as a proof of concept. It proves one thing: how far we can push parameter counts, and how far coding capabilities can be extended.
In that sense, it's akin to the kind of proof-of-concept Zhang and Perelman offered—it points the way for the field, telling later researchers, "This path is viable, and it can go far."
But it's not the kind of proof-of-concept that immediately changes how problems are solved. Fable 5's safety guardrails are too strict; its 30-day data retention policy has scared off compliance-sensitive buyers; and U.S. export controls took it offline for a while. Users grumbled that typing "Hey" burned through 847,000 tokens and cost $20—powerful, sure, but painfully expensive.
There's a world of difference between a prototype that proves an upper bound and something that can be rolled out to a production line.
III. AI's Second Half: From Benchmark Racing to Value Delivery
Fable 5's cold reception is not an isolated incident. It's a signal.
The AI industry is moving from a "capability race" to a "value validation" phase. A model can post sky-high benchmark scores, but if corporate customers won't pay, that "stronger" is a laboratory victory, not a commercial success.
The future competition is no longer about fighting over the second decimal place on leaderboards. It's about effective intelligence density per unit cost—how cheaply you can help enterprises get that 95% of work done. The remaining 5% can be left to Fable 5s to prove "how far humanity can go"—but don't charge ten times the price for that distance.
The true fourth-generation model will be born in the exploration of the sparse reward problem. It may not be the one with the most parameters, but the one that lets the boss close their eyes with confidence—a "digital employee" that doesn't need constant supervision. It may not be the smartest, but it will be the most trustworthy.
Until then, every "strongest" model is just an expensive firework in the lab.
IV. A Final Word
The industry must acknowledge this: overestimating the value of "stronger" models is, at its core, underestimating the weight of "error tolerance" and "supervision costs" in real business workflows.
Fable 5's lukewarm reception is a much-needed reality check for the industry. The era of pure parameter arms races is turning a page. Whoever figures out first that "reliable" is worth more than "strong" will have real pricing power in the next phase.
It's not about giving up on building stronger models. It's about not mistaking "stronger" for the finish line.
The finish line is removing supervision.
About the Creator
Jin
Writer of reamstories
https://reamstories.com/jin
Enjoyed the story? Support the Creator.
Subscribe for free to receive all their stories in your feed. You could also become a paid subscriber, letting them know you appreciate their work.
Comments
There are no comments for this story
Be the first to respond and start the conversation.