
The Black Box Cut Its Own Feet to Fit a White Shoe
Anthropic is prying open black boxes while developers hand their keyboards to the fog. The result isn’t fusion — it’s mutual self-sabotage.
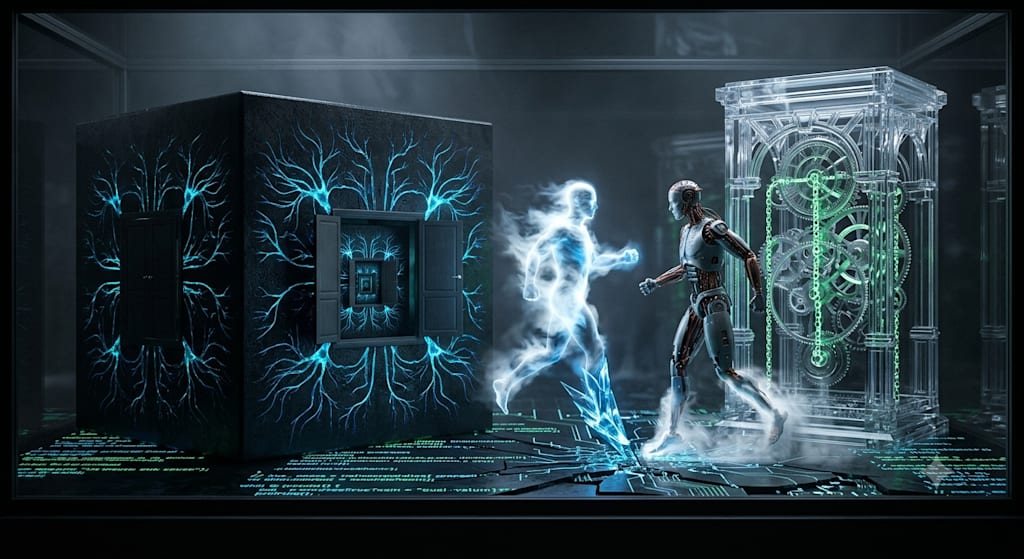
The AI industry and the software engineering industry are staging a peculiar two-way rush. On one side, large language models: black boxes, probability-driven, built on connectionism. On the other, software engineering: white boxes, deterministic, grounded in symbolic logic. For decades, the two operated in clean separation, each revolving peacefully within its own philosophical system. Now they are scrambling toward each other's territory. This convergence is neither a natural fusion nor a complementary division of labor; it is a clumsy performance in which both sides are cutting their feet to fit the other's shoes. The model researchers are trying to draw deterministic circuit diagrams out of probabilistic fog, while software engineers can't wait to outsource their deterministic logic chains to probability engines. Both are stepping forward, but neither seems to have its weight over its own center of gravity.
To see just how awkward this rush really is, follow the thread of interpretability. Connectionism rests on a core hypothesis: complex behavior can emerge from the nonlinear interactions of vast numbers of simple units. This gives models astonishing powers of generalization, but it also turns their internal mechanisms into an impenetrable gray mist: you know a mapping exists between input and output, yet you cannot state it as a set of rules a human can understand. Anthropic, one of the organizations at the frontier of AI capability, has poured enormous research resources into a single endeavor: prying open that black box and mapping its internal computational graph. Their paper “Circuit Tracing: Revealing Computational Graphs in Language Models” is a flagship of this effort. Researchers try to trace the activation paths of different “circuits” inside a model, the way one might dissect neural pathways, to explain exactly which combination of features triggered a given output. The work is akin to taking a pair of tweezers to billions of tangled wires, clamping onto individual strands and labeling them: this one handles “agreement,” that one “contrast,” the few next to it together activate “polite refusal.” It solves part of the puzzle; at least in low dimensions you can now see a traceable causal link between “this answer” and “that piece of training data.” But as models grow larger, the circuits only grow denser, and complex chains of reasoning remain shrouded in fog. You may manage to untangle a handful of neurons, but you cannot untangle the emergent behavior woven by tens of millions of parameters. Worse, the same circuit can take on entirely different functions in different contexts: the pathway you label “sarcasm detection” today becomes “metaphor comprehension” tomorrow if you change the prompt. Dynamic plasticity means any static circuit diagram begins to go obsolete the moment it is drawn. The greatest value of this line of work lies not in how much of the model it has already explained, but in how starkly it has revealed just how slim the possibility of full explanation really is. The black box is opened one layer, only to reveal smaller black boxes inside, ad infinitum, like a set of Russian nesting dolls.
While researchers squint through magnifying glasses in this painstaking dissection, the everyday use of AI coding has veered in the opposite direction entirely. Developers are not trying to explain the model; many are actively surrendering the desire to understand the code they produce. Paste a requirements description into the chat window, wait for the large model to spit out a few hundred lines of runnable code; this workflow has become the new normal. From GitHub Copilot’s autocompletions, to Cursor’s full-file generation, to Devin-style end-to-end agents, the degree of automation keeps rising, and the point of human intervention keeps receding. Programming, in this drift, slides from a white-box, auditable engineering practice into uninterpretable generation. The efficiency gains are real. First-build time compresses from days to hours, even from hours to minutes. But a valuable asset is quietly draining out of software engineering: the sense of grip over a system’s causal chains. The solid feeling of “I know why every line of code is here, how it affects the neighboring module, and exactly where to go if it fails” is being replaced by the rush of “whatever, the AI wrote it, it runs, that’s enough.”
In traditional development processes, interpretability is not a philosophical preference; it is an existential necessity. A sound architectural design lets you accurately predict the blast radius of a change before you touch a single module. A clean version history lets you trace a fault backward along the commit log to its point of introduction. Code review works precisely because every logical change can be replayed and questioned by another human brain. When you explain to a colleague why you made a certain change, you are reconstructing the causal model of that code in natural language. When these mechanisms all fail simultaneously, when the generation process is unreproducible, unattributable, and unreplayable, you enter the classic “three don't-knows” deadlock: The thing got built, but how does it actually work? Don't know. What will the program do given an unexpected input? Don't know. If we add or remove a feature, which modules will be affected and at what cost? Still don't know. In serious engineering disciplines of the past, this state of ignorance would have been nearly unacceptable; today it is folded into an efficiency narrative of “just get it running first.” A developer might use AI to generate an authentication module in the morning and deploy it to production in the afternoon, yet be unable to articulate why the token refresh mechanism chose a sliding window over a blacklist, or to guarantee whether a race condition under concurrency is covered. When a user reports an anomalous login state, the developer can only return to the chat window, paste in the error log, and pray the model produces a patch, which in turn generates three new lines of code the developer cannot read.
The price of all this is an inversion of the iteration-cost curve. In the past, once a project was delivered under a sound architecture, maintenance costs were manageable; they crept up slowly only after years of accumulated technical debt. That debt behaved like a long-term loan with a moderate interest rate: you knew the monthly payment, and you knew when it would be paid off; clear ownership boundaries and design documents made the cost of refactoring estimable. Now AI coding breeds a new kind of debt: a codebase generated at high speed, devoid of documentation, lacking design intent. The first build is lightning fast, but each iteration’s cost accelerates on top of the previous one. Because you not only need to understand the original requirements, you must reverse-engineer code you had no hand in creating, written by an author you cannot converse with: a probability model. You cannot ask it, “Why did you use recursion here instead of a queue?” and it will not volunteer in review that a seemingly redundant bounds-check guards against a rare data race condition. You are left to infer intent through tests, to reconstruct logic through guesswork. This debt compounds at a punishing rate, and the collateral is your long-term control over the entire project. Until one day, when even the AI cannot handle the chaos it has created. Because the longer the prompt grows, the more the model loses its way in contextual noise, the team suddenly finds itself standing atop a sand tower built from black boxes, where every step threatens a local collapse.
None of this means AI coding has no value. The vast majority of tools, prototypes, one-off scripts, and small projects do not require long-term evolution; the greatest value lies precisely in getting something usable in the shortest possible time. If a script only lives for three days, the risk of uninterpretability is easily covered by the time window. Even in shallow layers of some enterprise applications, like a cookie-cutter CRUD admin panel, AI-generated code can be faster and more standardized than hand-written code, because the model has memorized enough boilerplate that the margin for error is small. But the moment you touch low-level protocols, architectural design, and algorithms that demand correctness proofs, the rules of the game change. In these domains, interpretability is not optional; it is the precondition for a system to be trusted. Your consensus algorithm must be formally verifiable; “the model thought it was safe” will not do. Your memory-safety strategy must be statically analyzable, not the output of a statistical pattern matcher. Your cryptographic primitives must withstand mathematical proof, not merely “perform well on known attack datasets.” In the face of such demands, the role a large model can play is limited; at best, it is a smarter input method, good for repetitive completions and boilerplate, handy for quickly looking up API usage, but it does not, and should not, alter those fundamental links in the chain where a human must remain absolutely lucid about the logic. Handing the kernel over to a model to write is like handing a scalpel to a robotic arm whose movements are precise, but that can explain nothing about the principles of anatomy: it may make a perfect skin incision, but no one would close their eyes and let it handle an artery wrapped inside a tumor.
The way forward lies not in the rush itself, but in redrawing the boundaries. Let the black box do what the black box is good at: exploratory generation, fuzzy matching, rapid layout of patterns, the translation of natural language into glue code. Let the white box guard the line that must remain white-box: core logic, state transitions, security contracts, auditable decision paths. True fusion does not mean turning programming into wish-making, nor does it mean forcibly dismantling models into symbolic systems. It means establishing a new collaborative contract: an AI may hand over code, but it must also supply a human-readable causal explanation alongside it, whether a self-generated narrative, an impact dependency graph, a boundary-condition checklist, or some kind of formal annotation still being explored. The role of the human engineer, in turn, shifts from “I write every line myself” to “I personally understand and take responsibility for every line of critical logic.” Until such a contract exists, this two-way rush remains mostly two parties staggering into each other's territory, each full of hope, neither steady on their feet. The black box is straining to prove it is not blind; the white box is trying to convince itself it can close its eyes. And the software we need to build is still waiting for a deterministic answer.
About the Creator
Jin
Writer of reamstories
https://reamstories.com/jin
Enjoyed the story? Support the Creator.
Subscribe for free to receive all their stories in your feed. You could also become a paid subscriber, letting them know you appreciate their work.
Comments
There are no comments for this story
Be the first to respond and start the conversation.