
Synthetic Data Won't Save Us.
A Turing Award winner warns that the AI industry is running on a closed loop. The real path to AGI isn't about compressing human text—it's about letting machines get beaten up by the real world.
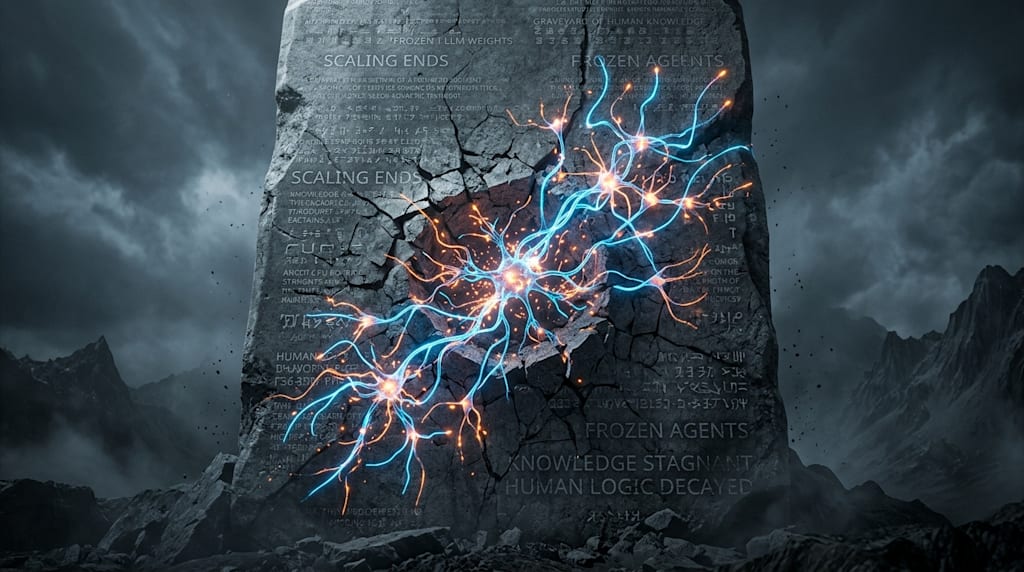
When Business Insider ran that piece, most people’s first reaction was: a Turing Award winner is against synthetic data.
That’s a misreading. Sutton isn’t against synthetic data. He’s against using static text generated by the model itself as a substitute for the independent feedback that comes from an agent interacting with its environment. Both are called “synthetic data” in name, but they are fundamentally different. If you stop at “Sutton opposes synthetic data,” you miss what he’s really saying – and that thing is continual learning. His verdict on today’s big-model companies is: you’re walking into a dead end, and you don’t even know it yet.
I. Three kinds of synthetic data – Sutton only objects to the first
To sort out Sutton’s stance, you only need to look at three categories.
The first kind: model talking to itself. An LLM generates ten million articles; another model scores and filters them; then the same LLM is trained on that output. This is a closed loop. No new information enters – only rearrangement and reinforcement of what’s already there. Sutton says the value of this data is “questionable,” which is already polite wording. In essence, you’re soaking the same stone over and over in a static pool.
The second kind: synthetic data with an external verifier. The model generates code; compilers and test cases tell it right from wrong. Here you have an extra ingredient: the external world. The compiler’s errors are objective; the test results are objective; the model cannot judge its own output by itself. Sutton approves of this path. Every team working on agentic RL today is essentially riding this wave.
The third kind: “imagined experience” based on a world model. This is the direction Sutton most wants to see. The agent learns a world model from real interaction, then uses that model for simulation and planning. But he adds a precondition: the world model itself must not be frozen – it must be continuously corrected by real experience. In other words, you can use simulated data, but the simulator must be constantly beaten by reality; it cannot spin its own stories and believe them.
So Sutton isn’t criticising the label “synthetic data” – he’s criticising the fact that the first mode is becoming the industry norm. It’s the cheapest, most convenient, easiest to scale – but its cost is that the system will never be corrected by an external world.
II. You’re compressing a graveyard of human knowledge, not intelligence
In a 2024 interview, Sutton said something that is rarely quoted. He said: “LLMs may be the peak of the human‑knowledge era, but they are not the end point of the Bitter Lesson.”
That sentence separates two things.
The first is compressing everything humans have already written into a model. That, LLMs do very well. All the text, code, and conversations on the internet are distilled into weights and then frozen. You ask it something, and it retrieves combinations of those weights to answer. It’s like a gigantic offline archive – fast retrieval, strong expressiveness.
But is that intelligence?
Sutton’s definition: intelligence is a goal‑directed system that acts on its environment and improves its future behaviour based on the consequences of those actions. Three keywords: action, consequences, improvement. An archive does none of these. An archive only stores and retrieves.
The problem is that today’s Scaling Law has pushed “compressing human knowledge” to its extreme, to the point where everyone mistakes that for the entirety of intelligence. OpenAI’s early devotion to The Bitter Lesson was read as one sentence: “more compute yields more generality.” But Sutton’s original essay also contained a second half: do not hard‑code human knowledge as the ceiling of intelligence.
The moment you finish training and freeze the weights, you are hard‑coding. You fix human knowledge up to that point and turn it into the model’s upper bound. No amount of inference or prompt engineering afterwards can break out of that frozen boundary. That is a structural bottleneck – and compute alone won’t fix it.
III. Plasticity – the metric you never talk about in public
In 2024, Sutton’s team published a paper in Nature demonstrating a phenomenon: standard neural networks, when continually learning new tasks, gradually lose their ability to learn new things.
They called this loss of plasticity. In plain terms, the model becomes stiff.
This isn’t theoretical speculation – it’s a reproducible experimental result. They even proposed a remedy: selectively reset inactive units in the network to preserve internal diversity. From then on, “plasticity” ceased to be a vague concept and became an engineering metric that can be compared across architectures and optimisers.
Interestingly, this metric has always existed inside the industry – teams just call it different things behind closed doors. Some say “post‑training headroom,” others say “fine‑tuning efficiency,” some call it “adaptability,” and still others “capability elicitation.” Different names, same core question: how much room does this model still have to be changed after its initial training?
But nobody talks about it publicly. Because the product form is a frozen model – users receive a static set of weights, and they don’t need to know whether it can still learn. The market doesn’t demand this metric, so it’s absent from leaderboards, model cards, and press releases.
Plasticity today looks a lot like long‑context capabilities in 2020 – researchers know it matters, benchmarks are starting to appear, but there are no unified standards, no competitive pressure yet. But with Sutton and Ilya both choosing the path of continual learning, that will change.
Tang Jie’s team recently ran a very straightforward experiment. GLM‑5.3 and GLM‑5.2 used exactly the same base model and parameter count – the only difference was that GLM‑5.3 underwent one month of long‑horizon reinforcement learning post‑training. Its AA benchmark score jumped from 53 to 60. Tang called it “post‑training elasticity” – in practice, that’s plasticity in an industrial setting.
Give the same base model one more month – how much new capability can you dig out? That’s the next competitive dimension.
IV. Two people, two paths, one landing
Sutton and Ilya both chose “continual learning,” but for different reasons.
Ilya’s reasoning starts from the upper bound. Static models have a ceiling, while real‑world agents need continuous adaptation – so models must keep learning after deployment. That’s the foundation of his startup SSI, where he bets on architectures like TTT (Test‑Time Training) that can update weights at inference time.
Sutton’s reasoning starts from definition. He has spent decades in reinforcement learning, viewing intelligence through the lens of “action – feedback – learning” cycles. For him, continual learning isn’t a new direction – it’s the rediscovery of what he’s always been saying. Last year, together with his former student Khurram Javed, he founded Oak Lab with a straightforward goal: build an AI agent that continually learns from direct experience, with a trillion parameters and power consumption squeezed down to 20 watts – close to the human brain.
Their technical paths differ, but they arrive at the same point: intelligence is not a file you hold at the end of training – it is something that grows over time through an ongoing cycle of action, feedback, and learning.
V. The day plasticity becomes a first‑class metric
Back to Sutton’s judgment.
He says that relying on the first kind of synthetic data to keep scaling is a huge mistake – not because he opposes data expansion, but because this path structurally sidesteps a core issue: your system is not connected to an external world that can correct it.
No correction, no learning. And without learning, scaling only compresses existing knowledge tighter – it does not create new understanding.
Plasticity is the metric that measures “how much you can still be corrected.” Open‑source models face this issue earlier than closed‑source ones, because the open‑source community more frequently takes base models for secondary training, fine‑tuning, and adapting to various vertical domains. When the continual‑learning paradigm truly takes hold – when users no longer just call a frozen model but instead let it keep changing in specific environments – plasticity will graduate from a hidden training‑team metric to a public first‑class metric.
On that day, model cards will have one extra line. That line won’t show MMLU scores or parameter counts – it will say just one thing: this model can still grow.
And the yardstick for who is really changing the industry will become equally simple: not who generates more data, but whose system dares to be beaten by reality, and after that beating, actually changes.
Sutton is doing that at Oak Lab. Ilya is doing that at SSI. Their methods differ, but their judgement is the same: the road of the past five years will not lead to AGI.
The road ahead is not in the text that humans have already written – it lies in the dents left behind when models crash into the world.
About the Creator
Jin
Writer of reamstories
https://reamstories.com/jin
Enjoyed the story? Support the Creator.
Subscribe for free to receive all their stories in your feed. You could also become a paid subscriber, letting them know you appreciate their work.
Comments
There are no comments for this story
Be the first to respond and start the conversation.