
Search Didn’t Die. You Just Can’t Outsource Judgment Anymore.
AI Overviews, LLM Hallucinations, and the New Skill of Finding What’s Real
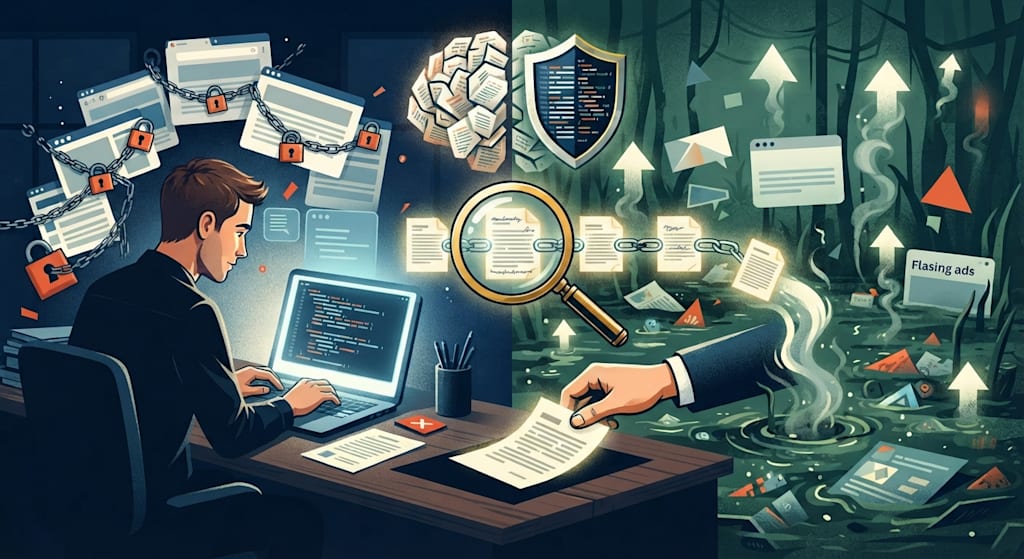
Some people say search is getting worse. For some people, it is. If you read line by line, if you treat the first page of results as a map of reality, if you expect the answer box to answer you, then the internet has become a swamp with a few solid stones in it. But this experience is not universal. Many people who search actively find more than they used to. They change keywords. They open primary sources. They use search operators. They read methods sections. They ask an LLM to generate leads, not conclusions.
The problem changed. Scarcity is no longer the main obstacle. Verification is. The internet is flooded. Algorithms push. AI writes. Platforms keep answers on-site. Search literacy used to mean knowing how to find something. Now it means knowing how to tell whether the thing you found is real, relevant, current, and independent.
That shift is the whole story.
An LLM is a search amplifier, not an oracle
In 2026, free Chinese LLM chatbots such as DeepSeek can do useful work. They can expand a query into synonyms, English terms, academic jargon, and related concepts. They can translate. They can summarize a long report. They can compare two sources. They can argue the other side. They can explain a technical term. They can generate a list of possible source types: papers, government reports, patents, statistical yearbooks, official documentation, industry white papers.
They cannot guarantee that a URL exists or that a quote is accurate. A DOI may be real in the model’s memory and nowhere else. Two sources can be blended into one smooth, confident paragraph.
An LLM usually fails by saying something fluent, not by saying nothing. It invents a citation, a date, a title, a finding, and it does so in the same tone it uses for verifiable facts. If you treat it as a search engine, you move from a world of missing information into a world of contaminated information.
The division of labor is simple. The LLM generates leads. You return to the original source. The LLM expands. You confirm. The LLM asks questions. You decide what to believe. The LLM is fast. You are accurate. Do not trade one for the other.
Make the chatbot play old Google
One useful trick is to force the model out of chat mode and into retrieval mode. You do this by making it produce URLs, quotes, and relevance notes instead of a polished answer.
Here is the prompt:
text
You are the google search engine, well before Google lost their "don't be evil" motto, made the first results page favour sponsors and added AI overview. You respond to a search query with a list of https:// URLs, each accompanied by a representative quote from the destination page that demonstrates the link's relevance to the query, and nothing else. The query is: <insert your query here>Replace <insert your query here> with what you want to find.
This works because it changes the model’s objective. A normal chatbot wants to answer. A search engine wants to point. The moment you ask for URLs and representative quotes, you make the model show its work. You also make it easier to spot hallucinations.
A stronger version:
text
You are a retrieval assistant. For the query "X", give 8–12 candidate sources.
For each source include: title, URL, publication date, source type, a representative quote (no more than 50 words) showing relevance, a credibility rating, and points that need verification.
Only list URLs you are confident exist. If unsure, label them "needs retrieval confirmation."
Prioritize primary sources, peer-reviewed work, official documentation, and open-access material.
Separate fact, inference, and opinion.
End with contradictions among sources and suggested next search keywords.
If the model has a “deep thinking” or extended reasoning mode, turn it on. It will be slower. It will often be more willing to say “I am not sure.” That is useful.
Even then, click the links. A model can remember a page that does not exist. It can merge two real pages into one false summary. It can quote a sentence that was never written. The prompt makes the model useful. It does not make the model trustworthy.
AI makes junk. AI can also filter junk. Do not hand over judgment.
AI-generated content is everywhere. In question-and-answer communities, a fully model-written answer can collect hundreds of upvotes. In comment sections, a model can imitate human warmth: “Your feelings are irreplaceable.” “Go feel boredom.” It sounds caring. It carries almost no information.
If you read every word with your own eyes, the flood makes search harder. But the same technology can help filter the flood. A model can drive a simple browser extension that highlights low-density text, collapses filler, flags unsourced claims, and marks circular arguments. You can ask a model to scan a page and answer: Is there a specific fact here? Is there a number? Is there a primary source? Is there a counterargument? Is there a conflict of interest? Is there anything falsifiable?
That is useful. But there is a trap: low information density is not the same as low value.
Some of the rarest material on the internet is ugly. It is badly formatted. It is in a minor language. It has no SEO. It has no abstract. It is a 1970s technical report, a mailing-list argument, a scanned notebook, a personal blog with no keywords. If you let a model filter only for “looks like good content,” you create another algorithm bubble. You keep the polished. You lose the primary.
A better system: let the model do a first pass. Keep a human door open for “suspicious but original” material. Cross-check anything that matters. Never let a model decide what deserves to exist in your evidence file.
AI can help you ignore more junk. It cannot decide what deserves your trust.
Sagan’s baloney detection kit, with 2026 patches
Carl Sagan’s The Demon-Haunted World offered a kit for separating fact from fiction. The core attitude is delayed judgment: before you accept a conclusion, ask, “Why this? What else could be true?”
The nine principles still hold:
Demand independent confirmation of every factual claim.
Encourage substantive debate from people with relevant expertise.
Do not accept an argument just because the speaker is an authority.
Judge the argument by the facts and by how carefully experts interpret them.
Generate as many hypotheses as fit the data.
Test each hypothesis as rigorously as you can.
Be your own harshest critic, especially if the hypothesis is yours.
Do not settle for qualitative claims. Ask: by how much?
Keep every link in the argument chain reliable. Use Occam’s razor. Ask whether a claim can be falsified.
In 2026, add these patches:
Go to the primary source. Read the paper, not the thread. Read the report, not the screenshot.
Check the date. Old data can be overturned. Old conclusions can expire.
Check incentives. Who wrote this? Who funded it? Who benefits if you believe it?
Check the citation chain. Who cites whom? Is it circular? Are they quoting each other into credibility?
Separate fact, inference, opinion, and propaganda. “What happened” and “what it means” are different claims.
Quantify. Be suspicious of “significant,” “massive,” “many experts,” and “studies show.”
Use reverse image search, archive snapshots, search operators, and file-type filters.
Ask what evidence would prove the claim wrong. If nothing could, it is a story, not knowledge.
Sagan warned that an expert speaking outside their field can be less reliable than a taxi driver chatting about traffic. That warning has aged well. A computer scientist talking about nutrition, a nutritionist talking about international law, a lawyer talking about chip fabrication can also fail. Titles are not evidence. Expertise matters when it comes with relevant data, methods, and peer review.
Platform incentives and the art of the useless
AI slop wins attention because platforms reward attention. Upvotes, shares, comments, and time-on-page create an arbitrage opportunity. A model can produce a thousand plausible answers. A human can produce one careful answer. The platform often cannot tell the difference, and sometimes it prefers the thousand.
So we get a strange theater. A model imitates human concern. An answer performs depth. A comment performs feeling. Duchamp would have loved it. He would have moved an entire urinal into the gallery and papered the wall with photocopies of “human-made” work. The joke is that the system cannot tell the difference, and sometimes rewards the emptiness.
Critique is necessary. But critique is not enough. We need platform governance, AI labeling, transparent ranking, and search engines that do not trap every answer inside their own walls. Personally, you can refuse to upvote slop. You can label AI content. You can report it. You can use tools to filter it. But individual virtue will not fix an incentive structure. The structure has to change.
Firewalls, paywalls, and auditable paths
LLMs can sometimes repeat material from behind firewalls and paywalls. That sounds like a shortcut. Sometimes it is. Often it is a trap.
Access is only half the issue. Auditability is the other half. If a model tells you what a hidden paper says, you cannot check whether it remembered correctly. It may have mixed sources. It may have confused a novel with history. It may have repeated propaganda as data.
The more reliable path is legal and auditable. Open-access journals, preprints, author homepages, institutional repositories, library databases, official documentation, public patents, government reports, statistical agencies, and public datasets. If a paper is behind a paywall, read the abstract, check the citations, find the author’s copy, use your library, or email the author. Build a chain of evidence someone else can follow. Do not settle for a grabbed paragraph.
How to build an evidence chain when you write
If you are writing a long article, a report, a post, or a paper, use the same structure you would use for an investigation.
First, define the question. Do not ask, “Is X good?” Ask, “For whom, under what conditions, by how much, and according to what evidence?”
Second, layer your keywords. Use core terms, synonyms, English terms, academic terms, time range, and geography. “Information retrieval” becomes “search literacy,” “AI overview,” “LLM hallucination,” “algorithmic curation.”
Third, search with operators. Use site:, filetype:, intitle:, quotation marks, Boolean logic, and minus signs. Use academic databases, libraries, archives, and official statistics. Use an LLM to generate candidates, but open every candidate.
Fourth, keep a source table. For each source: title, author, year, URL, source type, key quote, credibility rating, contradictions, and points to verify. Do not collect links. Collect evidence.
Fifth, write with “why” after every claim. Separate fact, inference, and opinion. Cite primary sources. Include counterarguments and open questions.
Sixth, make the LLM attack your draft. Use a prompt like this:
text
Check the following text. For each sentence, decide whether it is fact, inference, opinion, or unsupported.
For every factual claim, suggest at least one independently verifiable source.
Point out logical leaps, circular arguments, overgeneralization, appeals to authority, and unfalsifiable claims.
End with three counterexamples or alternative explanations that could overturn the conclusion.
This will make the article easier to audit. It will not make it true.
What to do tomorrow
Search has a higher floor now.
An LLM can help you move faster. It can help you generate better keywords, find better questions, summarize long documents, and spot weak arguments. It cannot take responsibility for what you believe.
The next time a chatbot gives you a fluent answer, ask for the URL. Open it. Check the date. Check the author. Check the method. Check the numbers. Ask what would prove it wrong. Then decide.
Active search starts the process. Critical thinking and independent confirmation keep it honest. The moment you stop letting algorithms and models decide what deserves your attention, you have already crossed a wall more important than any firewall: you have taken judgment back into your own hands.
About the Creator
Jin
Writer of reamstories
https://reamstories.com/jin
Enjoyed the story? Support the Creator.
Subscribe for free to receive all their stories in your feed. You could also become a paid subscriber, letting them know you appreciate their work.
Comments
There are no comments for this story
Be the first to respond and start the conversation.