
I Use AI Every Day. Here's Why I Still Don't Trust Its Judgment.
Karpathy's cognitive funnel explains the vertigo. The long tail explains the regret.
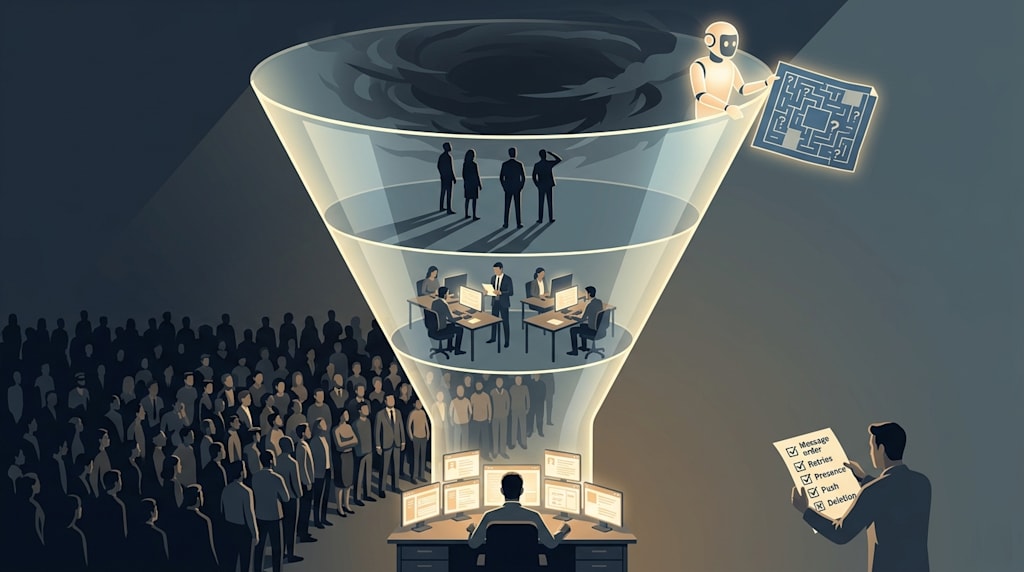
Last night I saw Karpathy's tweet. Some people made funnel charts. Some reposted it. I didn't feel vertigo.
I don't stand higher. I stand somewhere specific. An internal IM. A client PPT. A long-tail problem with a feedback cycle of several months. What I feel is regret.
Karpathy cuts the world into four layers. About 6 billion people have never touched an LLM. More than a billion occasionally use the free version, treating it as a smarter search engine. About 20 million professionals pay for frontier agents like Claude Code and Codex. They see a productivity surge in programming, math, and research. At the very top, maybe a few thousand people can access internal lab systems. They watch agent swarms collaborate, attack, defend, explore.
The chart isn't precise. The top should add total global population. The proportions should be steeper. But its value isn't precision. It reminds us that AI capability diffusion is extremely uneven. The cognitive gap is enormous. A few watch the storm from the summit. Most look up from the foot of the mountain.
The summit isn't complete intelligence either. Vertigo hides a judgment deficit.
After the Opus 4.6 and GPT-5.5 generation, at least in my direction, model upgrades hardly bring new help. It can write code. It understands concepts. Its judgment is too poor. The longer the tail, the closer its judgment gets to random guessing.
Ask it about architecture. It lists one, two, three, four, five, covering everything. Ask it about edge cases. It says concurrency, retries, idempotency, degradation. When it comes to end-to-end delivery, it gets lost among conflicting constraints. It doesn't know which constraint matters more in production, which degradation strategy is acceptable, which consistency model is worth the cost, which elegant solution will blow up in production.
Mainstream training is flawed. Too much post-training on search-like, verifiable tasks. Too little post-training on judgment.
Zero-day exploits matter. Few people care. Post-training on them every day makes benchmarks look good. It does not make products useful. The useful test is writing an internal IM end to end and passing acceptance directly.
At minimum, the system has to handle multi-device sync and message order, concurrent sends, clock drift, retries, search outages, presence outages, push outages, large-group fan-out, unread counts, synchronous versus asynchronous attachments, soft versus hard deletion, quoted messages, audit logs, new-member history visibility, kicked-user cache access, and rejoin permissions.
Ask an AI each of these. It talks like it knows. It works like it doesn't.
It has no overall standard of judgment. No continuous mapping from what the client wants to how each technical detail should be traded off. Only local knowledge, no global trade-off. Each step looks reasonable. Put together, it may not pass acceptance.
There is another bad trend. Models assume tests or human review will catch them. So they are not careful. They give a complete-looking plan. They ignore edge cases. They push judgment responsibility onto later tests or human review.
Not every task in the world has someone to catch you.
Take a client-facing PPT. You tell the AI what the client wants and what they don't care about. Even the strongest model can't map the client's needs to every detail. It can't maintain an overall standard of judgment. It writes beautifully. The logic flows. It doesn't know which page should be heavy, which light, which data point should stand out, which risk should be avoided, which promise must not be made.
Code and PPT are the directions where LLMs have seen the most training data. With this kind of judgment, for long-tail research with feedback cycles of several months, I don't dare imagine how bad it would be.
Companies are too impatient. Their eyes only see six months out. Projects that need a year to prepare data have feedback that is too slow.
Judgment training is slow. It needs long-cycle data, real-world feedback, human experts making trade-offs in ambiguous scenarios. It needs to separate what is right from what can run. Math problems have clear right and wrong. Code just needs to run. Judgment involves value ordering, cost constraints, risk appetite, user expectations, organizational capability. These are hard to verify automatically. Hard for RL reward functions to capture.
So everyone retreats to easily verifiable domains: search, math, code, zero-days. Clear reward functions. Suitable for RL. Good benchmarks. No one touches long-tail tasks.
Probably only when revenue peaks and stocks crash will they come back to think about judgment. Whether it will be too late by then is hard to say.
The last part of Karpathy's tweet is more important. He says the people who benefit most have two traits. They pay for the most frontier agentic models, like Claude Code and Codex. Their domain is programming, math, or research.
Original:
So that brings me to the second group of people, who both 1) pay for and use the state of the art frontier agentic models (OpenAI Codex / Claude Code) and 2) do so professionally in technical domains like programming, math and research. This group of people is subject to the highest amount of "AI Psychosis" because the recent improvements in these domains as of this year have been nothing short of staggering.
Why these domains? Clear, verifiable reward functions. Suitable for RL. Writing is a thousand people, a thousand faces. Hard to say what you like, others like. Math has clear right and wrong. Code just needs to run. Research subproblems can be verified by experiment. These directions have huge value. Models improve fast.
I happen to be in programming and research. Every day I run several AI agents at once. Now it is like commanding a PhD group plus several postdocs, advancing experiments at high speed. My personal efficiency is dozens of times higher than before. It brings several times the returns. So I pay $200 a month.
Vertigo happens in verifiable domains, on tasks with clear reward functions. Claude Code with Opus 3.5, thinking effort set to high, can melt problems that used to take days or weeks. The productivity jump is measurable.
Vertigo and regret are not contradictory. Two sides of one thing.
Vertigo comes from RLVR in verifiable domains. Regret comes from the missing judgment domain. AI is a lopsided giant. Strong in verifiable domains. Stumbling in overall judgment. It can melt programming problems. It cannot make end-to-end judgments for an internal IM. It can write papers. It cannot judge which direction is worth doing. It can generate PPTs. It cannot understand what the client wants.
The people at the top of the funnel are not seeing complete intelligence. They are seeing specialized intelligence shaped by reward functions. Very strong, but directional. Outside that direction, random guessing.
Karpathy's funnel diagnoses something else: in how many people's hands AI can be entrusted.
The test is whether AI can be entrusted after use. The next stage is judgment post-training: long-cycle data, real-world evaluation, human expert feedback, trade-offs under complex constraints. Whoever solves judgment opens the next layer.
Otherwise, the funnel gets steeper. Fewer people feel vertigo. More feel regret.
I want peace of mind.
I close a few agents. I open the acceptance checklist for the internal IM. First item: multi-device message order. The model gives another complete-looking plan. I delete it and write it myself.
About the Creator
Jin
Writer of reamstories
https://reamstories.com/jin
Enjoyed the story? Support the Creator.
Subscribe for free to receive all their stories in your feed. You could also become a paid subscriber, letting them know you appreciate their work.
Comments
There are no comments for this story
Be the first to respond and start the conversation.