
DeepSeek and the “National-Fate” Label: Three Things It Proved, Three Things It Didn’t
Homegrown talent reached the frontier. Cheap training eased the compute squeeze. Open weights traveled. The company did not kill Stargate, and it did not solve the chip problem.
On January 26, 2025, Feng Ji wrote on Weibo that DeepSeek might be a national-fate-level scientific and technological achievement. His reasons were concrete: the model was powerful, cheap, open source, free, connected to the internet, and built by a domestic team. A game developer working from product experience had touched a pain point deeper than the product. The year and a half that followed showed what the phrase was pointing at.
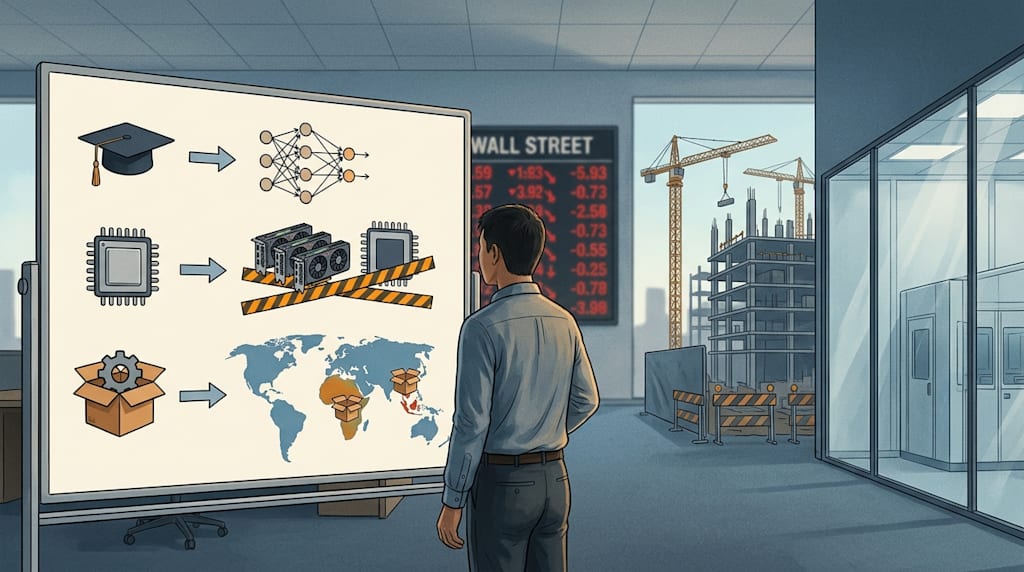
The label is not a coronation of one company. People accepted it because DeepSeek loosened three long-tight structural nerves at once. Could homegrown talent produce frontier work without an overseas training loop? Could algorithmic efficiency offset the chip blockade? Could China offer a global AI option that did not depend on U.S. APIs? Each answer would matter on its own. They arrived through one company, one model family, and one short window, which is why the phrase carried weight.
Start with the factual baseline. Liang Wenfeng was born in 1985 in Zhanjiang, Guangdong. He studied electronic information engineering at Zhejiang University for his bachelor’s and master’s degrees. Public records show no overseas study or work experience. DeepSeek hires mainly from domestic universities. Liang has said he prefers top Chinese graduates with little work experience. After R1 shipped in January 2025, Nvidia fell about 16.97% in one day, losing roughly $589 billion in market value. That was the largest single-day market-value loss for a U.S. stock. DeepSeek-V3’s pre-training cost was disclosed at under $6 million. OpenAI GPT-4’s estimated training cost was above $100 million. R1’s reinforcement-learning increment cost less. Its API price was about 94% below OpenAI’s.
Some claims need correction. “It killed Stargate’s $7 trillion” is too tidy. Stargate launched with a $100 billion initial commitment and a plan to reach $500 billion over four years. The project stalled for reported reasons: SoftBank and OpenAI disagreed over sites and key terms, lenders refused financing, and tariffs added uncertainty. DeepSeek’s low-cost shock weakened confidence in the brute-force compute buildout. Attributing Stargate’s trouble directly to DeepSeek turns a messy commercial and geopolitical fight into a smooth joke. “Every release knocks trillions off Wall Street” is also too broad. R1’s release caused a historic shock. Later updates did not repeat that scale.
The first nerve was the homegrown-talent loop. The Qian Xuesen question weighs on people because it points to a structural doubt. If frontier work always requires top overseas labs, multinational engineering systems, and globally mobile talent as intermediaries, then independent cultivation remains an unfinished promise. DeepSeek supplied traceable data. A 2026 Hoover Institution whitepaper at Stanford tracked 356 researchers behind seven core DeepSeek papers. Of that group, 53.5% had never been linked to an institution outside China across their recorded careers. They had no overseas study, no overseas publications, and no overseas employment. At the core-team level, 10 of 31 researchers had never left China. For DeepSeek-R1, the model benchmarked against OpenAI o1, one-third of the most core contributors were trained entirely inside China’s domestic education and research system. Liang’s own path follows the same shape: Zhanjiang, Zhejiang University, no overseas degree, then quantitative trading and compute accumulation before DeepSeek.
One precision point: a homegrown loop does not mean rejecting overseas talent. The same Stanford report found that the 80 DeepSeek researchers with experience at U.S. institutions had the highest citation counts. Most had returned to China. Among researchers with international mobility, 70.3% came back. The claim that fails is the implicit determinism that says frontier breakthroughs require overseas experience. DeepSeek turned “homegrown training, homegrown organization, frontier output” from a theory into a record supported by papers, models, and contributor lists.
The second nerve was the ceiling created by the compute blockade. U.S. export controls rest on a clear chain: compute is a hard constraint on AI training, so choking advanced chip supply slows the rise of model capability. The chokehold hurts. Its deterrent power comes from making people believe the pain cannot be bypassed. DeepSeek did not make chips unimportant. It changed the nature of the constraint through engineering facts. V3 trained for under $6 million and competed with closed models that cost more than ten times as much. R1’s reinforcement-learning increment cost less and came close to OpenAI o1. The gap came from mixture-of-experts architecture, multi-layer attention, training strategy, and low-level engineering. No single secret explains it. On the trading day after R1’s release, Nvidia fell 16.97% and lost $589 billion in a day. Broadcom, AMD, and TSMC fell together. Power suppliers fell harder. The market reaction included panic. It also marked a shift in belief: if algorithmic efficiency and architecture can offset part of the compute gap, then “stack compute, build superclusters, monopolize model capability” stops being the only credible path.
This does not solve the chokehold. Advanced fabrication, HBM, and the software ecosystem remain bottlenecks. Part of the deterrent power of the chokehold comes from the belief that no alternative exists. DeepSeek showed an imperfect alternative. The pain remains. The ceiling no longer feels airtight.
The third nerve was a second option for global AI infrastructure. R1 shipped the day after Stargate was announced. Confidence in “brute-force compute, centralized super-models, closed API monopoly” took a hit from the efficiency side. DeepSeek did not try to win the same race with less money. It released model weights under the MIT license. Anyone could download, modify, deploy locally, and build proprietary products on top. A country with limited resources no longer had to buy U.S. APIs to get frontier AI, and it no longer had to accept a dependent “compute for service” deal. Malaysia built national sovereign AI infrastructure around DeepSeek models, the first national-scale deployment of a Chinese AI model outside China. Microsoft estimated that DeepSeek usage in Africa in the second half of 2025 was two to four times higher than in other regions.
When AI moves from product to infrastructure, competition shifts partly from “whose model is stronger” to “whose rules become the access standard.” Closed models export services. Open models export the capacity to build. Open models earn less in the short term. They shape long-term position. The tools used to build hospitals, schools, and government services define those systems’ interfaces, dependencies, and direction.
What remains unsolved. The homegrown-talent evidence does not mean China’s universities and research system have no structural problems. It shows that frontier output can grow at the current system’s upper limit. The system itself is not complete. Efficiency gains do not erase the pain of chip controls. They change the constraint’s nature. Open-source expansion does not give Chinese AI global dominance. It proves an alternative path can work. Chip fabrication bottlenecks remain. HBM supply remains constrained. Basic software gaps remain unfilled. Global market access remains unresolved.
Liang’s own judgment is calmer than the external story: “What Chinese innovation lacks is certainly not capital, but confidence, and the knowledge of how to organize high-density talent.” The weight sits on “organizing methods are lacking,” not on “talent is lacking.” Breakthroughs in organizing methods are the hardest to plan and the easiest for an existing system to suppress.
The Fiat story keeps returning. An early Weibo account named “Program Little Prince” wrote on November 7, 2011: “Trapped in a no-man’s land for a week. Fortunately I got out. But my Fiat did not. It will remain forever in that boundless alpine grassland.” People give the story symbolic weight because it marks a way of working, not because it proves some mystic character test. Enter an area with no ready route. Accept the risk of losing your tools. Walk out. Policy cannot copy that method. An inspirational slogan cannot simplify it. It remains the part of “organizing high-density talent” that is hardest to institutionalize.
The phrase “national-fate-level” does not mean one person changed the country’s fate. It means a set of things believed to require external conditions held under domestic conditions. Homegrown talent produced a model near the frontier. Algorithmic efficiency opened room to maneuver under compute limits. Open-source strategy gave China a rule-shaping role in global AI infrastructure that it did not have before. None of the three is finished. All three moved from “impossible” to “proven feasible.” A road believed closed was shown to be passable. The person who showed it stood on the extension line of domestic education and domestic organization. That is what people point to when they use the word “national fate.” It does not promise smooth sailing. It changes the factual baseline for the next argument about whether something can be done.
About the Creator
Jin
Writer of reamstories
https://reamstories.com/jin
Enjoyed the story? Support the Creator.
Subscribe for free to receive all their stories in your feed. You could also become a paid subscriber, letting them know you appreciate their work.
Comments
There are no comments for this story
Be the first to respond and start the conversation.